Services Data and Artificial Intelligence
From Enterprise Data Sources to a Reliable Analytics and AI Foundation
icitech helps enterprise organisations integrate data from ERP, CRM, POS, IoT, and application systems into an accessible, observable, and quality-controlled analytics and AI platform. The objective is not simply moving data: it is establishing a data layer that is genuinely ready for BI, machine learning, and generative AI — built to serve the decisions your organisation needs to make.
01 Context
Why Does Data Slow Down Decision-Making?
AI and BI investments most often stall not at the model or dashboard stage but at the data layer. The same customer may exist under different identities in the CRM, the ERP, and the loyalty programme; it is rarely clear whether source systems have been updated; a pipeline failure quietly becomes an incorrect report. The analytics team rebuilds data from scratch for every new question, and the AI project never advances beyond proof of concept into production. The business consequences are straightforward: confidence in reports falls, decision cycles lengthen, and the data team spends its time correcting problems rather than generating value.
02 Context
icitech's Approach to Data Engineering
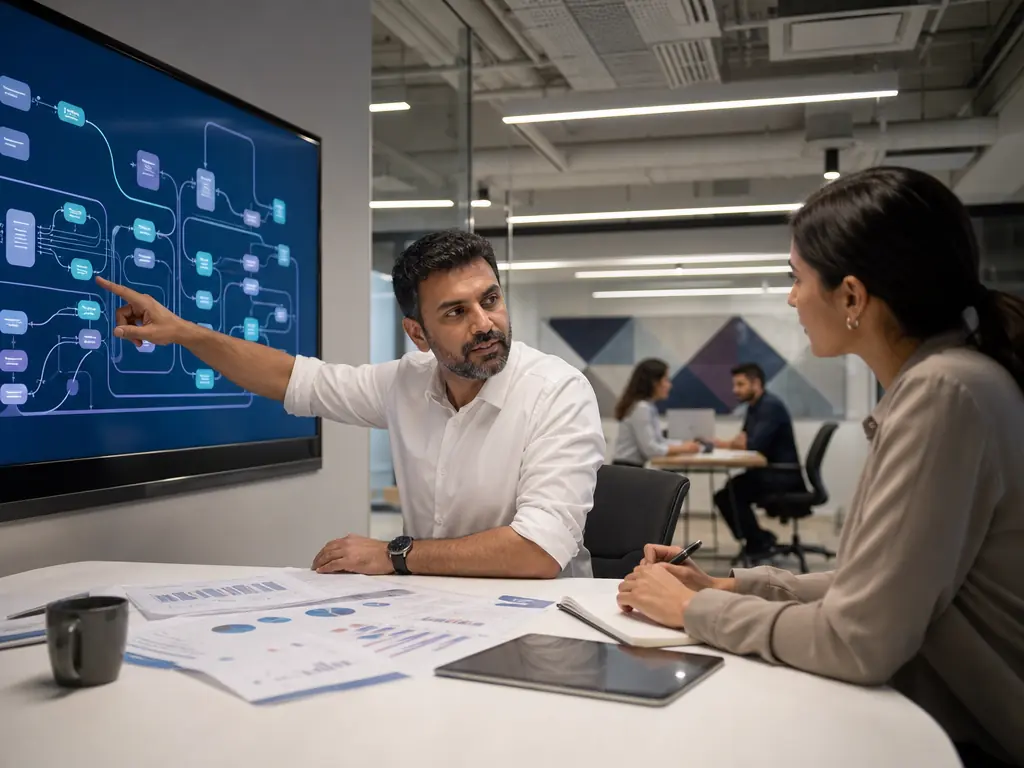
icitech's data engineering approach begins with a thorough understanding of the organisation's existing data environment and proceeds by tying each step to a concrete business use case. The first stage surfaces source systems, data owners, update frequencies, and critical business entities. A target data architecture is then agreed, aligned with the organisation's cloud or on-premises platform preference. On that foundation, ingestion, transformation, quality control, and serving layers are designed together as a single coherent programme.
Data Integration and Pipeline Design
Ingestion patterns — API, batch, or file transfer — are shaped by the requirements of each project. Schema changes, latency tolerance, and error handling are designed in from the outset rather than added later. As raw data is transformed into business entities and metrics, reusable calculations are defined within a standard semantic model, so that the same KPI is calculated with the same definition across every system.
Data Quality and Governance
Data quality is applied across the dimensions of completeness, deduplication, validity, freshness, and referential consistency, calibrated to the risk profile of each use case. Pipeline health, data freshness, and the downstream impact of source changes are monitored continuously to prevent silent errors from reaching reports or models. Data ownership and lineage are modelled to meet the organisation's governance requirements, including those arising under UK GDPR where applicable.
Serving Layer for Analytics and AI
An appropriate access layer is built for dashboards, machine learning, LLM retrieval, or operational applications. In generative AI assistants, retrieval quality depends directly on ingestion design and metadata structure, so AI-ready dataset preparation is treated as an integral part of the data engineering programme rather than an afterthought. Cloud data architecture across AWS, Azure, and Google Cloud is configured to align with the organisation's existing ecosystem.
03 Scope
Enterprise Use Cases
In retail, data from the CRM, POS, and mobile application is consolidated into a unified customer model, with the loyalty programme and AI recommendation engine drawing on the same data definitions. In the energy sector, meter and IoT data is combined with ERP cost and facility master data to produce analytics datasets segmented by site, period, and operational context. In an AI knowledge platform scenario, approved document sources are brought into an ingestion pipeline with defined access roles and metadata, so that a generative AI assistant operates over a controlled, governed dataset.
04 Context
Deliverables
Depending on project scope, deliverables may include a data source inventory and landscape analysis, target data architecture, source-to-target mapping, ingestion and transformation pipelines, a canonical entity model, data quality rules and validation dashboard, an analytics data mart, AI-ready datasets, metadata and lineage documentation, an access model, pipeline monitoring, and a technical runbook. A use-case-driven, incremental approach limits the risk of large-scale scope drift and unnecessary platform complexity.
05 Context
Why icitech?
A data platform does not generate value in isolation: it must be considered alongside the AI, mobile, web, and enterprise applications that consume it. icitech's capabilities in software engineering, API development, cloud, and product development allow data pipelines to be connected directly to end users and operational workflows. This combination of modern software engineering, data engineering expertise, data governance fundamentals, and analytics automation ensures that data creates value where it is used, not merely where it is stored.
06 FAQ
Frequently Asked Questions
Timescales vary with scope and the number of source systems, ranging from a few weeks to several months. An initial working pipeline is typically delivered by the end of the first sprint.
We have integration experience with widely used ERP platforms including SAP, Oracle, and Microsoft Dynamics 365. For bespoke or less common systems, a technical discovery phase is used to assess compatibility before work begins.
Automated profiling tools monitor continuously for anomalies, gaps, and inconsistencies in the data. Issues identified are prioritised jointly with the technical team and business unit representatives so that remediation reflects actual business risk.
We support both deployment models and design hybrid architectures where required. The appropriate approach is determined by the organisation's security requirements, cost constraints, and infrastructure maturity.
The serving layer we establish gives ML models low-latency access to clean, structured data. Feature store and model registry integrations are addressed within the same scope where needed.
We do not require any particular tooling; a governance framework can be built using your existing licences or open-source options. What matters is clarity of policy and accountability, not the choice of tool.
We manage high-frequency IoT streams using real-time and micro-batch processing architectures. Scalability is factored into capacity planning at the design stage rather than retrofitted later.
You will receive documented pipelines, a data dictionary, quality reports, and a production-ready analytics layer. A structured knowledge transfer ensures your team can manage and extend the platform independently.
We adapt the project model to your team's existing capacity and can provide operational support where needed. The aim is to strengthen your team's capability, not to create a dependency on external resource.
LLM-based applications are particularly sensitive to context quality and data freshness, which makes the retrieval layer and metadata management critical rather than optional. We design the infrastructure with those requirements in place from the start.